We were already using subagents at work, but I went all in when I took the Claude Academy subagents course. I built eight across two repos, and in about 18 hours the jobfit ones ran 27 times, 11 of them as real agents. They found things I had missed, got it wrong a couple of times, and writing their rules uncovered bugs before I ever ran them.
A subagent is a separate instance you hand a task to. It runs in its own context, does its thing, and only the summary comes back to your main conversation. All the noise along the way, the files it read, the greps, the searches, stays out.
While I was taking the course, I kept thinking about Naruto training with shadow clones: he makes a whole bunch of them in a field, each one tries to cut a leaf with its chakra, and when they vanish, whatever each clone learned comes back to him. A subagent is that, with two differences. The original doesn't get everything the clone went through, just the summary. And Naruto's clone remembers everything Naruto lived through; the subagent remembers nothing from your conversation. It knows what its file says and what you pass it when you hand over the task.
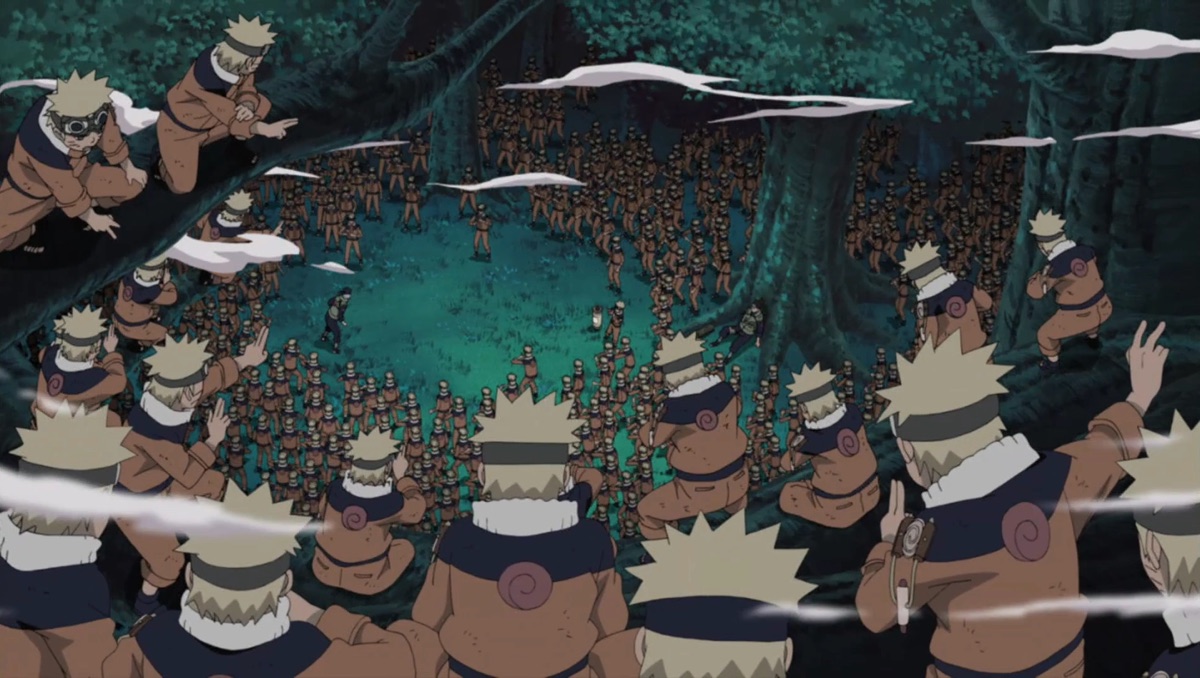 Open image full size
Naruto against Mizuki, the first time he uses shadow clones. Naruto, Studio Pierrot.
The second difference is the one that matters.
The mistake is making them experts#
The first thing you want to write is "you are a React expert, review this code". That doesn't work: the model already knows React. A subagent that calls itself an expert can't do anything your main conversation couldn't do just as well. And yet the course's own example starts with "You are an expert code reviewer".
What the model doesn't know is that in my repo, a hardcoded /blog/ sent Spanish readers to the English blog. Or that adding a link to the nav pushes the headings under the bar on mobile. That isn't in any dataset. It's in my bug history.
My site-reviewer has a note next to those two rules saying they already happened. It isn't a Next.js expert. It's the one that remembers every time I screwed up.
And here's the uncomfortable part: my subagents are useless to anyone else. They're full of design tokens from my CSS, route names, decisions that only apply to my two repos. Even if you copied them into your repo, they'd just be noise to you. That isn't a design flaw, it's the design.
The eight#
Four in this blog's repo and four in jobfit, the project from my post about evaluating a prompt.
| Agent | Repo | What I delegate | Model | Writes |
|---|---|---|---|---|
| post-editor | blog | review a post before sharing it | opus | no |
| post-translator | blog | translate a post into the other language | opus | yes |
| prod-checker | blog | confirm a deploy reached production | sonnet | no |
| site-reviewer | blog | review a PR against the repo's rules | opus | no |
| docs-drift-auditor | jobfit | check the numbers in the README, the SPEC and CLAUDE.md against the database | sonnet | no |
| eval-disagreement-analyst | jobfit | understand why the scorer and my labels disagree | opus | no |
| repo-rules-reviewer | jobfit | review code changes against the repo's rules | opus | no |
| source-assessor | jobfit | assess whether a new job posting source is usable | sonnet | no |
Seven out of eight don't have Write. The only one that does is the translator. That wasn't an accident: the course keeps insisting you give each one only the tools it needs, and when you sit down to decide, it turns out almost none of them need to write.
But not having Write isn't the same as being read-only. All eight have Bash, and you can write a file with Bash too. The site-reviewer says in writing that it never edits files, and in its only run it created two test scripts inside the repo and then deleted them. The seven without Write are read-only because I ask them to be, not because they can't write.
I applied the other rule without noticing, and I'm writing it down now that I see it: opus where judgment is the product, sonnet where the work is verification. The editor judges a piece of writing. The disagreement analyst interprets why a scorer and I don't agree. Those go on opus. The prod-checker runs curls and compares strings, and the docs-drift-auditor compares README numbers against the database. That doesn't need opus.
Besides these eight, at work we use subagents day to day for specific tasks. I can't share details about the code, but I can say what we use them for:
- Reviewing a PR before human review, against existing behavior, looking for what could break.
- Tracing a field from the BFF request to the UI, with every transformation and the file where it changes shape.
- Turning a ticket into a plan: which files to touch, which APIs are involved and which tests to add, based on the code instead of guessing.
- Finding the cause of a bug without fixing it yet: I ask for the three most likely causes and what evidence would rule out each one.
They work for the same reason mine do: they know that code and they have a concrete job, not an expert title.
What my subagents found#
I ran the post-editor on my first post, the one about how this blog is built, a post I'd already published and had also reviewed with another Claude session. So, two pairs of eyes on it already. And that first time it wasn't even the agent: the session predated them, so I asked a generic subagent to read the post-editor file and follow it.
It found a contradiction inside the post itself: the table said "Dependencies: none" and two paragraphs later it said "10 direct dependencies". Neither I, who wrote it, nor the reviewer caught it.
It found that my numbers were measuring something else. The 9 KB was only the compressed HTML, and I'd measured the 10-second build with a warm cache. Later I measured it cold: 14.5, 11.7 and 10.8 seconds.
And it found this, which is the best one: I had written "Google says officially" about whether a blog does better on a subdomain or in a subfolder. I'd added that phrase at the other reviewer's suggestion. The agent searched the web, and no such Google documentation exists, just statements from John Mueller. One reviewer slipped in an unverified claim, and another agent, which hadn't been part of the conversation, caught it.
That's exactly what the course says about why a separate reviewer works better: whoever wrote something doesn't review it well, because they read it with the memory of having written it.
Once it was a real agent, I ran it twice on my second post, the jobfit one. The first run came back with "Don't share yet" and four substantive problems. The second, on the fixes, caught a sentence that was no longer true: I said the 135 score rows were still in the database, and the re-score had replaced 39 of them.
The prod-checker has four runs, the first one also a generic subagent following its file, and it found nothing in any of them. But its most useful rule came from something that actually happened: a session insisted three times that my deploy hadn't reached production, and it was caching on its end. Now that agent has it in writing that, before blaming the cache, it should search the live HTML for a string the deploy introduced.
And the site-reviewer gave me its most useful finding before it ever ran. While writing its SEO rules, I realized my tag pages with noindex were still showing up in the sitemap. The bug came from writing the rule, not from running the agent. That distinction seems more important to me than everything else: writing the constraint forces you to go check whether you're meeting it, and that's worth it even if the agent never runs.
The same thing happened in jobfit. Reviewing the four agents' files before their first run uncovered a badly worded rule in my CLAUDE.md, which meant the reviewer would flag, on every review, a file that did exactly what I wanted to allow; that two agents described how the prompt is versioned incorrectly; and that my CLAUDE.md said the rubric lived in a folder that doesn't even exist in the repo. All of that was committed thirteen minutes before the first run.
jobfit: 27 runs in 18 hours
Each agent's description tells Claude when to use it without me asking: the reviewer before every code commit, the auditor before touching the docs and after every change that moves a number. So in about 18 hours they ran 27 times: 15 by the repo-rules-reviewer, 11 by the docs-drift-auditor and one by the disagreement analyst. The first 16, again, were a generic subagent following the file.
The best finding came from the reviewer. I had added a --labels-only flag to score only the 79 labeled job postings, and all the tests passed. But the command read the flag and dropped it before the query, so it would have scored 202 postings instead of 79. To give you an idea, scoring 202 postings, when I did it later in two runs, cost $1.81. The tests didn't see it because they called the function underneath directly, not the command. The reviewer caught it before I spent a cent.
The auditor found that the README said the August 23 queue had 45 postings, when that day's file had 5, plus other numbers that no longer matched the database.
And it also got something wrong. In that same run it said a 5.3% in the README couldn't be reproduced from any data: it had divided by the wrong number. I took it at face value, it went in as an error on the list of verified facts I put together to write the previous post, and a later run disproved it. An agent caught the mistake, but it went through me without me checking it.
82k tokens that were really 480k#
Here's the part the course doesn't cover.
The pitch is that subagents save you context. That's true, but only for the main thread, and they don't save you from your own sessions. Each subagent runs its own requests.
And those requests add up to more than it looks like. When a run finishes, Claude Code tells you how many tokens the subagent used: 82k for the post-editor run on my first post. That number is the size of the context at the end, not what it processed. To get there it made 8 requests, and each one resent everything accumulated so far: about 480k tokens total, almost all of them read from cache. And the site-reviewer was the clone that vanished without bringing anything back: it made 38 requests, went past 2 million tokens and got cut off when it hit the plan limit, without delivering the report.
In jobfit, the 27 runs processed almost 35 million tokens, 92.7% from cache. The one that took the most was the docs-drift-auditor, the very one I put on sonnet because it only verifies: 81% of the tokens and 388 of the 503 requests, with a single run of 6.5 million. Claude Code's own usage panel suggests putting a cheaper model on simple subagents, and I did. But a cheaper model makes each request cheaper, it doesn't remove requests, and each one resends the whole accumulated context. What weighed the most was how many times it resent everything, not the model. And just like with Naruto, the exhaustion comes back too.
In Claude Code's usage panel, weekly view (it's approximate, it only counts sessions on this machine, and it's the week I built the agents): 93% of my usage was above 150k of context, and 67% in sessions longer than 8 hours. In other words, subagents should keep the main thread from growing, and my context blows up anyway. The problem isn't the pattern. It's that I leave sessions open all day and don't run /clear when I switch topics.
The contradiction I do have#
The course warns against sequential pipelines, and my workflow is one: edit, translate, review the PR, verify production. But each step reads the file from the repo, not the previous step's summary, so nothing gets lost in the handoff.
What I still don't know#
The source-assessor has never run, and the disagreement analyst ran only once, so what I say about them counts as design, not evidence. The rest have a track record: nine runs on the blog and 27 in jobfit.
I've already had a report go wrong both ways. With the jobfit 5.3%, the agent was wrong. In the review of this very post, the editor flagged some builds I had actually measured as made up, because the data I gave it was incomplete: there, the agent did its job right with a half-done brief. That's why I still read their reports with suspicion.
For now, here's where I land: a useful subagent is so specific it's useless to anyone else. It isn't an expert, it's a shadow clone that only knows what I left it in writing.
If you built a subagent that only works for your repo, tell me what you delegated to it. And if you want the next post, there's the RSS feed.